Security | Threat Detection | Cyberattacks | DevSecOps | Compliance

CVE-2026-109618 and CVE-2026-109619 (PHP2Shell): Two Critical PHP Remote Code Execution Flaws

The PHP security team has announced an emergency security release for Wednesday, October 21, 2026 at 14:00 UTC. It addresses two critical vulnerabilities, both rated CVSS v4.0 9.2. The vulnerabilities are tracked as CVE-2026-109618 and CVE-2026-109619. Both bugs are described as remote code execution issues, meaning an attacker could get their own commands running on a vulnerable server. The route to disclosure was messy.
Enforcing the highest level of security in your environment with Keeper's Risk Management Dashboard

The Keeper Risk Management Dashboard is a powerful feature of the Keeper Admin Console that provides comprehensive security posture information covering end-user deployment, utilization, cloud configuration, and event monitoring. This critical data helps administrators ensure that risks are remediated and compliance is enforced effectively. The Risk Management Dashboard monitors key metrics and leverages Keeper Security's Benchmarks to enforce the highest level of security in your environment across all users and devices.
Bitsight AI Mode: AI-Powered Cyber Risk Intelligence & Agentic Workflows

Meet Bitsight AI Mode, a new way to investigate cyber risk, prioritize critical exposures, and accelerate security decisions using AI-powered intelligence and agentic workflows. Built directly into the Bitsight platform, AI Mode combines conversational AI with automated, multi-step analysis to help security and risk teams turn complex cyber risk data into actionable insights. With Bitsight AI Mode, you can.

The Best AI Governance Platforms for Financial Services in 2026

Most governance platform comparisons written for financial services lead with the EU AI Act high-risk regime. For a bank deploying credit scoring today, that is the obligation furthest from biting, and the ones already in force get less attention than they deserve. ‍ The criteria below follow the provisions rather than the subject areas, with dates attached, because the sequence they arrive in decides what a platform has to do first. ‍

Cyber Risk Register vs. Vulnerability Register

The two registers hold different objects, run on different clocks and answer to different people. Where they are treated as one list at different levels of detail, items get counted twice and others fall between them. ‍ A vulnerability register holds findings on assets and numbers in the thousands. A cyber risk register holds loss scenarios and numbers in the tens. Neither is a summary of the other. ‍

There's Something Missing in the Discussion About AI in Vulnerability Management

The platform determines what is known. AI helps determine what it means. Technology solution providers across virtually every industry are racing to add AI, in some fashion, to their offerings. Vulnerability management providers aren’t immune, either. They’re racing just as fast as the rest of them, sometimes faster. These vendors are embedding copilots, assistants, and agents powered by technologies like Anthropic Claude, OpenAI GPT, and Google Gemini.

How to conduct a data risk assessment that drives action

A data risk assessment evaluates where sensitive data lives, who can reach it, and what happens if that access is misused. It creates value only when teams assign and track remediation; without current access data and live verification, organizations can't show that exposure has fallen. 75% of sensitive data exposures begin with compromised identities or misconfigured permissions, according to the Netwrix 2026 Data and Identity Security Report.

What an AI Agent Registry Should Record

Seven fields carry an agent registry, and they split into two kinds. Some a person has to state, because the answer exists only in somebody's intention. The rest can be read from systems that already hold them. ‍ Which kind each field belongs to decides whether the registry drifts. Typing an observable value creates a record that was accurate on the day somebody typed it, and recording a declared value is the only way to capture it at all. ‍

Top-Down vs Bottom-Up Cyber Risk Quantification

Run both approaches against one company and the figures differ, which is expected. The useful part is that they differ in a predictable direction, which makes the distance between them informative rather than embarrassing. ‍ Bottom-up tends to come in lower and top-down higher, for reasons that follow from how each is built. Knowing which way each one leans is more useful than choosing between them. ‍

DRTV Agency Contracts: Risk Mitigation Guide for CMOs

CMOs managing high-stakes advertising campaigns often find themselves accountable for every dollar spent on direct response television. Scrutiny comes quickly when a commercial underperforms or a media buy yields fewer leads than anticipated. One overlooked contract clause or missed reporting standard can expose the brand to unnecessary financial risk. The best shield against budget surprises and campaign breakdowns is a contract tailored to the realities of DRTV advertising, with safeguards built around performance, compensation, intellectual property, and exit options.

The New Frontier of Malicious AI: What Underground Forums Tell Us About the Evolution of Cybercrime Tradecraft

Public discussion of AI-enabled cybercrime tends to lean heavily on vendor marketing and speculation about future capabilities. We wanted to measure what criminal practitioners are actually discussing, what tools they prefer, and where their attention is shifting.

The Best Cyber Risk Register Software in 2026

Most register comparisons rank products on fields, workflow and integrations. A more useful test is which decisions the register can settle, because a register that cannot settle a decision is a record of one made elsewhere. ‍ Five decisions get asked of a register. Which risk to treat first, how much to spend treating it, whether to accept it, whether to transfer it, and whether the treatment worked.

Mapping AI Interaction Monitoring to the OWASP Top 10 for LLMs

Interaction monitoring covers four of the ten risks in the 2025 Top 10 for LLMs and generative AI applications well, three partially and three not at all. The split is not arbitrary, and the line it follows tells a buyer more than the coverage count does. ‍ Monitoring observes systems being used. Several entries on the list describe defects in how a system was built, which no amount of observation at the point of use will surface.

Governing AI Coding Agents on Developer Laptops

A coding agent on a laptop runs as the developer. It reads the same keychain, carries the same tokens and appears in every downstream log under the same name. The identity record is accurate and it cannot answer the question governance needs answered. ‍ Every control keyed to identity therefore operates on a merged subject.

Cybersecurity Budget Planning for 2027

A budget presented as a total invites one question with two answers, approve or reduce. A budget presented as a ranked list invites a different question, which is where to draw the line, and that is a decision a board can make rather than a negotiation it can only win or lose. ‍ The ranking comes from one calculation per candidate control. Expected loss before, minus expected loss after, divided by cost. Order the list by that ratio and the budget builds itself, including the part that says stop.

The Best AI Agent Risk Quantification Tools in 2026

Search for agent risk quantification tools and most results are risk assessment tools. Questionnaires, maturity scores, compliance trackers and templates, all producing an ordinal rating. A rating ranks one agent against another. It does not tell anybody what to spend, what to insure or what to stop. ‍ The separating question is whether the output arrives in currency.

The Best AI Governance Platforms for Mid-Market Companies

Enterprise AI governance guidance assumes a review board that meets monthly, an independent validation function, an impact assessment per system and somebody whose job title contains the words AI and compliance. A company of three hundred people has none of those and is governed by the same regulations. ‍ The difference runs deeper than budget. Enterprise programs are assessment-led, which scales with headcount because every system needs an assessor.

The Cost of a Mid-Market Ransomware Attack

The extortion demand is the figure that gets quoted and rarely the largest line. Downtime, restoration, forensics, legal hours and notification each contribute, and for a mid-market company the regulatory components behave in a way that catches finance teams out. ‍ Reporting deadlines do not scale with headcount.

DragonForce Ransomware Profile: From Affiliate Program to Cybercrime Cartel

When people discuss DragonForce, two distinct names usually come up: DragonForce Ransomware and DragonForce Malaysia. To set the record straight, the ransomware operation isn't necessarily the same entity as DragonForce Malaysia. DragonForce Malaysia operates as a politically driven hacktivist collective known for pro-Palestinian campaigns, defacing websites, launching DDoS attacks, and leaking data.

How AI Audit Trail Confidence Grows With Each Connected Source

An audit trail is usually judged by how much it contains. The more useful question is how many innocent explanations it rules out, because a record that admits a benign reading supports an assertion rather than a conclusion. ‍ Each source added to a trail removes an alternative explanation rather than adding detail. Confidence therefore climbs in steps rather than smoothly, and three sources of the same kind are worth less than two of different kinds. ‍

MCP Gateway Security Controls for AI Agents

The Model Context Protocol states plainly that it cannot enforce these security principles at the protocol level, and that implementors should follow best practices in their integrations. Every control an organization gets therefore comes from where it places the gateway and what it does there. ‍ The protocol publishes its own security best practices document, currently at revision 2026-07-28, naming the attacks a deployment has to handle.

How to Monitor AI Interactions on Employee Devices

Monitoring has to happen on the device, because three categories of AI use never reach the network in a form anything can inspect. Local models run without leaving the machine. Desktop applications that pin their certificates sit on an inspection bypass list by design. A laptop on a home connection routes through nothing the organization operates at all. ‍ The uncomfortable part is that the first two are deliberate. Somebody approved the bypass, and the approval was correct on its own terms. ‍

Supabase Data Exposure | 16,000+ Open Databases and What Security Teams Can Do

We found more than 16,000 Supabase databases sitting wide open, and over half held personal data like names, phone numbers and passwords. The organizations behind them ranged from a valet service to a government consulate, and in many cases the owners never checked the settings AI wrote. What is the Supabase data exposure? Anyone visiting these sites could read the data in their databases. Many belong to vibe-coded apps, where AI coding tools often handle the database setup.

Risk Acceptance Has a Shelf Life: Notes from the Aviation ISAC Cybersecurity Summit

The first Aviation ISAC summit, a little over a decade ago, was about forty people in a room in Miami, hosted by the Health ISAC. This year’s conference in Vancouver hosted more than five hundred: airlines, airports, OEMs, suppliers, and government, all in one place for three days. Many in the audience were new to the conference. One of the opening speakers asked first-timers to raise their hands, and a lot of hands went up around the room.

Managing Third-Party Cyber Risks in Complex Supply Chains

Big breaches often start somewhere boring. A refrigeration contractor with remote access to the network (Target, 2013). A file-transfer tool nobody on the security team had thought about in years (MOVEit, 2023). A compression library buried four layers deep in a Linux distro. Meanwhile most vendor reviews still run on an Excel questionnaire that gets filled in once, filed and forgotten, and attackers know that perfectly well.

The Interconnected Security Program: Managing Risk Across Cybersecurity Domains

Cybersecurity programs have become increasingly specialized and become a rather expansive enterprise responsibility. Protecting a modern organization can involve identity, endpoints, networks, applications and APIs, cloud infrastructure, data, threat intelligence, detection and response, governance, risk and compliance (GRC), incident response, and cyber resilience. Each discipline brings specialized technologies, processes, and expertise to the security program.

Preparing for an ISO 42001 Audit Rather Than Reading About It

Plenty of material explains what ISO/IEC 42001 contains. Clause by clause, control by control, with a checklist of documents to prepare. The standard itself is a management system specification rather than a control catalogue, and the distinction is where audit preparation goes wrong. ‍ The checklists share one omission.

Calibrating a Cyber Loss Model to One Environment

A model built on industry data produces an industry answer. The obvious next step is to calibrate it to the specific environment, and the obvious place to start is the threat picture, because every organization believes its own is distinctive. ‍ It is the wrong parameter to start with. Some inputs should stay general, some must be local, and the ones that must be local are the harder ones to observe, which is why they get left at a default. ‍

Power Grid Attacks Aren't New. So Why Are They So Electric Right Now?

In late July 2026, 36 municipal waste and water systems across Minnesota were targeted in a cyber attack. The attackers targeted Programmable Logic Controllers (PLCs) that were in control of pressure, pumps, and chemical dosing. When the news broke, it felt like it was everywhere. This was an attack on critical systems, systems that we require and use daily. But cyberattacks on U.S. critical infrastructure systems like water, hospitals, sewage, gas, and electricity aren’t new.

Frontier AI Impact Series, Part 2: How Attackers Choose Their Door | Bitsight

How much attention are you giving the doors outside your own network? Your security team may be watching a high-profile CVE closely. An attacker might be looking at a stolen session, a phishing kit, or a supplier with slower response times. Frontier AI gives them more ways to explore those routes. Bitsight’s Emma Stevens breaks down that decision in part two of our video series.

The Attribution Trap: What Happens When Threat Actors Manipulate the Story of an Attack?

Imagine waking up Monday morning to discover you’ve been breached. The attacker has stolen sensitive financial data, set up persistent access, and then greets you with a lovely ransom note at 8:00 a.m. demanding money in exchange for the encryption key. Immediately, you reach out to your security operations team, and they quickly begin assessing the damage and reviewing the breadcrumbs left behind.

AI Governance Where the Regulator Also Runs the Market

AI governance evidence is usually prepared for a neutral reader. A regulator with no stake in the market, an auditor with no competing product, an examiner who gains nothing from what the documentation contains. ‍ In securities and derivatives markets that assumption does not hold. Exchanges and clearing organizations register as self-regulatory organizations, and most of them operate the market while regulating its participants. The reader of your evidence is also an operator. ‍

The Cyber Risk Number That Goes to Three Different Committees

An exposure figure is produced once and read three times. The audit committee sees it, the risk committee sees it, and the board sees it, and each is answering a different oversight question. ‍ The figure travels well and the reasoning behind it does not. What arrives at the third reading is a number with no assumptions attached, and by then it reads as a fact. ‍

AI Governance Evidence That Costs Nothing to Produce

The usual case for governance return is that it speeds up enterprise sales, because buyers ask security questions and a prepared answer closes faster. It is true and it is the weaker argument. ‍ The stronger one is loss avoidance, and almost nobody makes it, because it needs a loss figure that most governance programs do not have. What makes it affordable is a distinction between two kinds of evidence. ‍

What an AI Correlation Rule Cannot See

A correlation rule can be tuned. The window can be widened, the join key improved, a source promoted from optional to required. Each of those is a parameter with a defensible setting. ‍ What remains after all of it is the residual, meaning the events that would produce a finding if a source existed for them, which is a form of residual risk expressed in detection terms. Naming it is the question an auditor asks after being shown a detection, and the answer is not a tuning exercise. ‍

A One-in-Hundred-Year Cyber Loss Is Not a Schedule

A quantification exercise reports a one-in-hundred-year loss and the figure travels well. It sounds precise, it sounds severe, and everybody in the room believes they understand it. ‍ Most of them do not. The phrasing describes an annual probability and it reads as a statement about timing, and the two produce different decisions from the same number. ‍

Frontier AI Impact Series, Part 1: Why Attackers Stopped Waiting for Zero-Days | Bitsight

Frontier AI can shrink weeks of vulnerability research into exploitation in hours. What does that mean for the flaws your team deprioritized years ago? Bitsight’s Emma Stevens, Senior Threat Intelligence Advisor, breaks it down in the first video of our new series.

The AI Incident Reporting Duty Nobody Can Date

Compliance content answers the question of when an obligation starts. For the serious incident reporting duty in the AI Act, the honest answer is that it is disputed, and the dispute is not a failure of research. ‍ Two readings of the text point in different directions, neither is obviously wrong, and no authority has resolved it. What follows is the reasoning on both sides and what to do without picking one. ‍

Cyber Loss When the Inventory Itself Perishes

An outage is normally modeled as deferred revenue. Production stops, orders wait, operations resume and some of the backlog is recovered by running longer. ‍ Where the inventory perishes, none of that applies. The stock is destroyed during the incident, restoring the systems does not bring it back, and running longer afterward produces new product rather than recovering the old. ‍

Cyber Loss When the Stolen Asset Is a Trained Model

A trained model is expensive to produce, cheap to copy and impossible to recall. Where one is taken, the organization still holds it, and the loss is not that the asset is gone. ‍ What ends is exclusivity. Lost exclusivity is a different quantity from a destroyed asset, it carries no notification obligation, it appears in no breach cost dataset, and most estimates therefore put it at zero by omission rather than by judgment. ‍

The AI Marking Deadline That Applies Only to Systems Already Running

Transitional relief normally works one way. A new rule arrives, existing products are carved out or given years, and anything built afterwards complies from the start. ‍ The marking obligation for synthetic content inverts that. Article 50 has applied since 2 August 2026, and a targeted transitional period gives extra time to systems that were already on the market rather than to new ones.

Reading AI Use From the Browser When the Network Sees Nothing

A session to a sanctioned AI provider looks the same on the network whichever account it ran under and whatever was in it. Transport encryption means a proxy sees a connection to an approved domain and a payload size. ‍ Which is fine until somebody asks whether an exposure is reportable. The question turns on three facts the network never held, and none of them can be reconstructed from a log afterward. ‍

Cyber Loss in Rail and Signalling

Cyber risk in transport is usually framed around a collision. Signals manipulated, a train sent onto occupied track, an accident caused deliberately. ‍ Signalling is built to make that outcome unavailable. Any failure forces the system into its most restrictive state, so a compromise produces a halt rather than a crash. The loss is the halt, and rail is unusual in already having a published price for one. ‍

How to Evaluate and Choose the Best TPRM Software in 2026

Evaluating third-party risk management (TPRM) software in 2026? Every platform says it tracks your vendors. What a demo will not show you is whether it finds those vendors on its own, including the AI tools and shadow IT nobody logged, or waits for you to type them in. This video follows one vendor from the day it shows up in your environment through five criteria for judging any TPRM platform, and the question to ask a vendor on each one.

DEF CON 34: Lessons Beyond the Conference

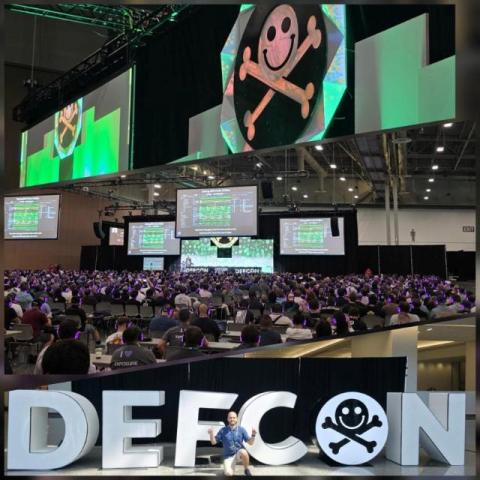
Being part of the cybersecurity community means more than simply following the news or reading security research. It is about getting involved, having conversations, sharing experiences, discussing problems, and learning from peers who face similar operational challenges. Of course, all of this comes with an investment of time, energy, and a full day of travel to reach one of the world’s largest hacking conferences: DEF CON in Las Vegas.

The Cyber Risk Inputs That Move the Answer Most

A cyber loss model has dozens of inputs and every one of them can be argued about. Record counts, downtime costs, control effectiveness, secondary loss factors, event likelihoods. ‍ A few of them determine the answer and the rest barely move it. Knowing which is which tells you where estimation effort belongs, and more usefully which disagreements about the model are not worth having. ‍

Reconciling an AI Risk Estimate Against What Truly Happened

A model produces a figure, an event happens, and somebody asks whether the figure was right. It is the obvious question and it has almost no published answer, because the comparison is harder than it looks. ‍ A single realized loss cannot falsify a distribution. If a model puts a one percent chance on exceeding a threshold and the threshold is exceeded, the one percent case occurred, which is what the model said would sometimes happen. ‍